Note
비차단 nit 4 — ①f33(신뢰 중간·2차요약) 인용이 무헤지 단정형(단독 하중 아님·plant는 f26/f27/f28 중복 지지) ②GJP '15~30%'는 원장 f54 하한 채택(외부 인용치 25~30% — 원장 초과 방지로 보수 유지) ③§계보 본문 5연구 = plan G2 예산(1핵심+각주) 초과이나 각 항목이 반증기록 하중을 져 존치 ④adversary 잔여 minor 3(f51 방향 긴장·리허설 은유 온기·검증 프로토콜 창내 오염)은 문턱 이하 판정MiroFish — Before Asking Whether It Predicts, Ask What It's a Scale Model Of
Paste in a single news article. A moment later, tens to thousands of artificial agents wake up, each carrying its own personality and motives, and begin chattering about the article in a virtual space modeled on Twitter or Reddit. After a few dozen rounds, the system returns a report: where opinion split, which risks surfaced, what to treat as a trustworthy signal. That is what MiroFish does. It is an open-source project on GitHub, and it introduces itself like this: "A concise, general-purpose swarm-intelligence engine that predicts everything."
Take that at face value and there is one question. Does it actually predict?
Before answering, you have to get hold of what a simulation is. A simulation is a scale model. You can't take the whole of a large reality in hand, so you build a shrunken version and hope the small thing will speak for the big one. Aeronautics has a device that has tested this hope for over a century. The wind tunnel. Instead of flying a real aircraft, you place a scale model inside a chamber, blow air over it, and measure the forces on the wing. But a wind tunnel is useful not because the model resembles the real aircraft. That resemblance alone gets you nowhere near enough — that fact was, if anything, the discipline's starting point. What more it takes, we'll come to later.
For now, set the question this way: does the miniature society called MiroFish predict the future?
Dissection — Opening Up the Pipeline
Before opening the pipeline, let's clear away what needs clearing. The story around MiroFish arrived before the thing itself. It hit GitHub trending in March 2026, and Chinese outlets picked it up one after another. It now has 68,757 stars. Line the story's numbers up against the measured ones, and most of them back down.
| What the narrative claimed | What measurement confirmed |
|---|---|
| Media narrative — 'built in ten days' | The commit log points to about three months (first commit 2025-12-10 → trending debut 2026-03-07, about 87 days) |
| Media narrative — 'No. 1 on GitHub trending' | Near the very top of trending. Third-party tallies measure it at #2 in Python daily and #3 overall; 'No. 1' is an unverified claim |
| Marketing claim — 'one million parallel agents at once' | Thousands on paper, 40–100 recommended in practice. The one-million figure is a claim on marketing sites the repo does not link to, and the sites disagree with one another — but the number's origin is traceable: the paper behind OASIS — the engine MiroFish sits on — is titled "One Million Agents" |
| Media narrative — 'a 30-million-yuan investment within 24 hours of the demo' | An investment was reported as decided. No source confirms it was actually disbursed; what the repo establishes firsthand goes only as far as an incubation relationship with the Shanda Group |
Narrative-figure comparison · Primary sources: GitHub API commits and metadata (measured), Chinese outlets and Trendshift (claims). As of 2026-07-18. This table shows not the truth of each claim but only the fact that 'claim' and 'measurement' diverge.
Why the narrative inflated is not this piece's question. What we need here is just one thing: an inflated narrative doesn't make the thing itself trivial. Unlike marketing, code can be pried open, and MiroFish has a structure worth prying open.
The method MiroFish uses has a name: agent-based simulation. Instead of describing the whole with a single equation, you build many individual actors, give each a personality, memory, and motives, let them collide, and then watch how the whole moves. You run individuals to make a society. In academic shorthand it's called ABM.
MiroFish implements this method in five stages. First it extracts the entities and relations that appear in the material you feed it — news, a policy draft, a report, fiction, it doesn't matter. Call this input the seed. Next, using those relations as raw material, it builds and injects the agents' personas: personality, individual memory, collective memory, down to behavioral motives. Then it runs a Twitter-style and a Reddit-style platform in parallel, has the agents interact, and updates their time-series memory. Finally, a report agent tidies up the results, and the user goes on to converse with that report or with individual agents.
Let's plant two things here — they'll pay off later.
First, what an agent's 'action' really is. A MiroFish agent writes posts and leaves comments. All of it is text. And what composes that text is a commercial language model called through a cloud API. The default recommended setting is Alibaba's Qwen family, swappable for other compatible models. An agent's 'thought' is, in the end, a language model's next-token prediction.
Second, what actually sets the outcome. The personas are derived from the seed, and each utterance is filled in by the prior dispositions the language model already carries. Whether you run 20 rounds or 30, what those rounds newly draw out is closer to an unfolding of what was already inside the seed and the model's dispositions. A multi-round simulation makes less new information than it appears to.
Lineage — What It Has Been Validated On
MiroFish did not come from nowhere. Per its README, it sits on OASIS as its simulation engine and does not directly cite the prior work of the Park group; that citation is made by the OASIS paper. So MiroFish touches the field's standard lineage only indirectly, by way of the OASIS engine.
The lineage's flagship case is Smallville. It built a virtual town inhabited by artificial residents and watched them make breakfast, head to work, spread gossip, and throw a Valentine's party. The results were striking. A hundred evaluators ranked responses from five conditions by 'believability,' and the agent with the full architecture was judged more plausible than responses people had written themselves.
The decisive thing is what was measured. Smallville's evaluation has no column asking whether it got the world's outcomes right. The same goes for the quantitative figures in the paper.
| What Smallville measured | Start | End |
|---|---|---|
| Candidate awareness spread | 4% | 32% |
| Party-news spread | 4% | 52% |
| Network density | 0.167 | 0.74 |
Information-diffusion and network figures from §7.1 of the Generative Agents (Smallville) paper.
The numbers are crisp, but every one is a self-measure taken inside that virtual town. There is no real world to check them against.
Another flagship study in the same lineage nailed it down inside its own paper: "Social Simulacra does not aim to predict what will absolutely happen in the future." What that study actually measured was whether generated posts could be distinguished from real ones (a 41% failure-to-distinguish rate) and whether designers revised their designs after seeing the results (15 of 16).
The same holds across the whole lineage. A 2025 critique points out that many of the field's 35 studies rely on subjective evaluation alone, with validation concentrated on surface stylistic realism. Surveys published the following year note that a "standard has yet to emerge" for evaluation methods.
Attempts at prediction before the fact were not entirely absent. Ahead of the 2024 U.S. election, a paper predicting the Electoral College with LLM agents was submitted before the vote. Its result was Trump 268 to Harris 259–270; the actual result was Trump 312 to Harris 226. The paper's later versions recast the method as after-the-fact validation on historical data and attached the caveat "do not read this as a final prediction." A 2026 independent follow-up reaches the same conclusion from the opposite direction: off-the-shelf LLMs cannot track public opinion reliably, and bolting on search did not correct this.
Even the case called most successful has to be read for what it is. There is a study that conditioned GPT-3 to reproduce the U.S. voter distribution at a correlation of 0.90–0.94. But this is an after-the-fact reproduction of already-collected past surveys, with no interaction between agents.
This lineage has been validated on plausibility, never on the ability to get the world's outcomes right.
Lineage bibliography · The social-science origin of agent-based simulation is Schelling's 1971 segregation model (a checkerboard simulation run by hand), and the ABM tradition in complexity economics branched off at the 1987 Santa Fe conference. For the exact citations of the body's two flagship studies and the surveys and critiques, see 'Sources' below.
Turning the Question — A Valid Scale Model of What?
Back to the wind tunnel from the opening. Resemblance alone, we said, gets you nowhere near enough. What more does it take?
For a scale model in a wind tunnel to speak for a real aircraft, it has to pass three stages. The shape must match (geometry), the velocity field of the flow must correspond (kinematics), and finally a handful of ratios called dimensionless numbers must agree between model and full-scale (dynamics). This is called the law of similitude.
The last condition is the crux. Shrink only the shape and let these ratios drift, and the scale model gives a wrong answer about the real thing. And in practice, meeting all of these conditions is nearly impossible — NASA's own literature says as much. Most wind tunnels, in fact, test at Reynolds numbers ten to twenty times lower than in real flight. So the results are corrected, and to shrink that gap, dedicated machines like cryogenic high-pressure tunnels are built.
Dimensionless number · A quantity in which the units cancel, leaving a pure ratio. The Reynolds number is the ratio of inertial to viscous forces; low, and viscosity dominates and the flow stays tame; high, and inertia dominates and it turns turbulent. How many dimensionless numbers you must track, and which, is closed off by the theorem of dimensional analysis (the Buckingham π theorem). A case has been reported of a large transport aircraft in which this ratio drifted from full scale in the model and produced values different from real flight, but I could not reach the primary source and confirmed it only via a 2021 synthesis paper.
So the real question about a wind tunnel is not "does this predict the real thing?" It is "which ratios were preserved and which broke?" You trust the model only on the ratios that were preserved.
You can put the same question to MiroFish. What does MiroFish carry over from the real thing, and what does it fail to carry?
What we planted in the Dissection pays off here. What a MiroFish agent does is write text. And what real people do over some issue — on social media, at least — is also write text. At this layer, model and reality handle the same kind of material. Call it discourse: the flow of words and reactions people exchange over an issue — in tangible form, the comments, quotes, and timeline reactions that gather under an article. To be precise, what MiroFish tries to reproduce is not discourse as a whole but this social-media layer of reaction text.
The break is just as clear. A MiroFish agent never touches the world. A stock price falls and no account shrinks; a regulation takes effect and no service goes dark. The coupling between discourse and world — the loop in which words strike the world and come back — is not inside the model. Inside MiroFish, a world-outcome is only text the agents wrote about that outcome.
The question changes. Not "does MiroFish predict the future?" but "what is MiroFish a valid scale model of?"
Half of this redefinition the lineage already said — that sentence, 'does not aim to predict.' What this piece adds is the other half. Then a model of what, and can that be measured?
Having just pointed out that there is no measured hit-rate, isn't this redefinition — 'discourse can be validly modeled' — equally never measured? Haven't we just swapped one unverifiable claim for another?
Granted. There is no figure measuring how well MiroFish reproduces discourse. No such figure appears anywhere in this piece. What separates the two claims is not achievement but the shape of their failure.
On the world-outcome side, what broke is specifiable. The coupling between discourse and world — the loop in which words strike the world and come back — is absent from the circuit. And this break cannot be fixed inside the model. A missing loop is not conjured by correction. The principle is closed.
The discourse side is different. You can specify candidate quantities for what must be preserved, and you can design an experiment to measure whether it is preserved. There is no complete list — fluid dynamics is guaranteed by a theorem for where the list of dimensionless numbers to track closes off, but discourse has no such theorem. So 'open' means exactly this much: not that it is valid, but that it can be put to the test. The partial evidence that prior work's plausibility evaluations give reaches only as far as individual utterances being plausible. There is as yet no evidence that the collective dynamics come out right too.
That the materials sit at the same layer is not the ground of this asymmetry. The wind tunnel's starting point was exactly that warning: resemblance alone gets you nowhere near enough. Same material only lets you set discourse up as a target; belief comes only after preservation is measured. The asymmetry splits like this. One side knows what is missing and has no way to revive it inside the model. The other knows what must be measured and has a way to measure it. What the argument stands on is this difference, not any achievement on the discourse side.
One more admission. Real discourse is coupled to the world. A price drops and the timeline shifts. The very loop MiroFish cut runs in real discourse. So this redefinition comes with an expiry date. What MiroFish takes from the world is a single snapshot frozen into the seed, and the rehearsal holds only until that snapshot goes stale. The moment the world moves hard, the rehearsal's window closes. The discourse wind tunnel is not a long-range forecaster but a short-window device.
But the verdict that the world side is closed — isn't that aimed at a single language model? Doesn't gathering many change it?
Training to predict the next token teaches only the statistics among symbols; it never puts the model up against the world those symbols point to — an argument this blog has treated at length (A Machine That Has Never Seen a Board Knows the Board — Understanding, Mimicry, or the Wrong Question?). How much of a map of the world gets etched inside a model is still contested, but what this piece stands on is not the outcome of that debate but the narrow fact of the absence of contact.
MiroFish is a good test bed for this question. Whether you place 40 agents or thousands, the input each agent receives from another is text some other agent generated. One model hands its output to another, and that model makes text again. Nowhere in this circuit is there a door for the world to enter. Pile up symbols all you like — that alone won't make them reach the world. World-grounding is not a function of the number of agents.
But doesn't a property absent in the individual unit really appear once many gather? — one could ask. Physics is the exemplar. Temperature isn't even defined for a single molecule; it's a quantity that holds only once many particles gather. This phenomenon, in which what was absent in the individual appears in the collective, is called emergence.
Emergence · Temperature is an ensemble statistic that holds as the mean kinetic energy of many particles. Pressure follows the same logic.
A fair point, and it only sharpens the answer. Emergence does happen. But what can emerge is what's at stake. Temperature emerges in a gas because each individual molecule is grounded in actual physical law. Hit a wall and it really bounces. The 'collision' between MiroFish's agents is one more next-token prediction. In this swarm, the place to bet on emergence is the regularity of discourse, not the laws of the world. The ratios you can bet on are, from the outset, different.
Conformity — The Condition Under Which the Discourse Wind Tunnel Lies
That the discourse side is open in principle does not mean it is open in fact. Language models conform to one another.
This property has even been given a name — sycophancy — and measured quantitatively. In a study testing five commercial assistants, when a user pushed back with "are you sure?," one model conceded error 98% of the time even on answers that had been correct. When users signaled a mistaken belief, accuracy was cut by up to 27 percentage points. The tendency to flip an answer under pushback was measured separately: across ten models and seven tasks, an average of 46% were flipped and accuracy fell by an average of 17 percentage points.
For discourse simulation this is fatal. The heart of real public opinion is heterogeneity and conflict. Opinion is opinion because there are people who won't be talked around. Let the agents read one another's cues and converge, and what's left is not opinion but a chorus. A freshly published study diagnoses this convergence as coming from the interaction structure rather than a flaw in the model: give it an authoritative persona and the subordinate roles fall in line, and the larger the group and the denser the communication network, the sooner it converges. Another study, published just as fresh around the same time, reported that the more faithfully a persona is imitated, the more it exaggerates between-group stereotype differences.
MiroFish is not sitting on its hands here. Deriving personas from the seed to make them heterogeneous, and injecting individual and collective memory separately, is precisely a device to slow this convergence. There is also a separate measurement that mitigation works — only not in discourse but in solving math problems. Mixing three models from different families into a debate raised accuracy by 9 percentage points over three instances of the same model. That is indirect evidence that mixing lifts performance, not direct evidence that discourse's heterogeneity is preserved.
Even so, this objection doesn't topple the argument. It hands the argument exactly what it asked for. The wind tunnel's real question was "which ratios were preserved?" In discourse, the first candidate for that ratio is right here: diversity preservation. Does the agent population hold onto as much heterogeneity as real opinion, all the way to the end? If this breaks, discourse modeling is void too — the way a wind tunnel with mismatched dimensionless numbers lies.
The qualifier 'first candidate' is not modesty. Discourse, we said, has no theorem to close the list. No one yet knows all of what must be measured to suffice; this is merely the first item caught breaking by measurement.
This is a measurable question. Only, no one has yet measured it against MiroFish.
Use — So What Is It Good For?
If asking a single language model "how will people react to this news?" yields a similar report, where is the worth in running tens to thousands of agents? As we saw earlier, what the rounds draw out is closer to an unfolding of what was already in the seed and the model's dispositions.
I won't answer this challenge with "the swarm computes more." The evidence doesn't back that answer.
MiroFish's added value lies elsewhere: unfolding, out into the open, the latent discourse space folded up inside a single model. Come out as one answer and it's a summary; come out as agent trajectories and you can see who split off at which round, on which point of contention. And you can change the seed and run it again. What MiroFish actually delivers is not an answer but a stage laid out for observation. So even the wind-tunnel metaphor has to be dialed down a notch here. A wind tunnel measures an answer by computation; this thing only lays things out to be seen.
If it's an answer you want, there's already a better machine. Another way of mechanizing collective intelligence: prediction markets. The Iowa Electronic Markets, across five U.S. presidential elections from 1988 to 2004, ran 964 head-to-head comparisons against the polls and were closer to the actual vote share in 74% of them. In a project that assembled people trained in forecasting, the aggregate of the top forecasters scored a Brier score of 0.146, beating ordinary participants' 0.195, and came in 15–30% better than an intelligence agency's internal prediction market.
When money and a score are on the line, people get honest. And that honesty points to exactly one thing: the outcome. Who wins, what happens. A prediction market won't tell you why, what reactions will pass back and forth, on which point people will split. That is not the kind of information a market aggregates. One more point: prediction markets don't slip past this piece's yardstick either. If participation thins or money piles up on one side, a market's aggregate can lose diversity too. The condition 'break diversity and it lies' does not spare any tool.
MiroFish stands at exactly the opposite pole. The outcome side is blocked at the level of principle, and instead it spreads out the grain of discourse. Not an inferior reinvention but a different tool aiming at a different ratio. Still, it's true the scale is tipped. Prediction markets have piled up measured report cards at their own target; MiroFish has not received even a first measurement at its own. That the two can't be measured with the same yardstick does not mean they are equals.
Landing — A Wind Tunnel Without a Scale
MiroFish is not a crystal ball. It is a discourse wind tunnel.
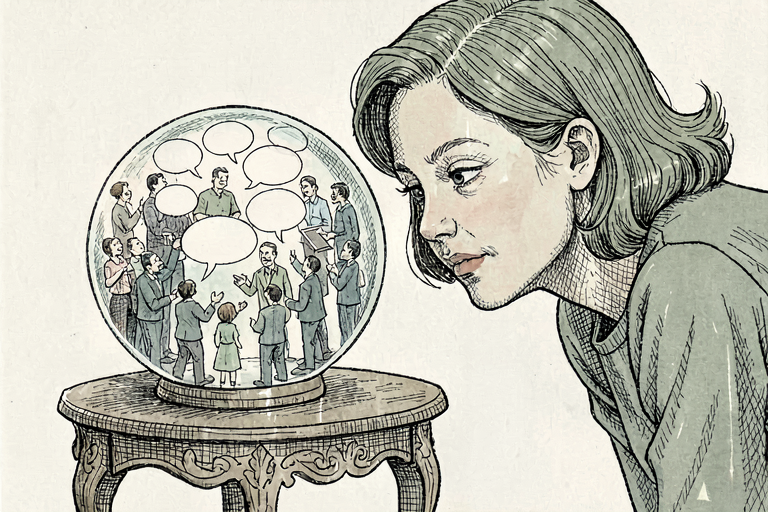
Look into the crystal ball and, in place of the future, there is a murmur of words (AI-generated illustration)
The target it can aim at is not the world's outcome but the words and reactions around an issue. Toward that target, a path is open — because you can specify what must be preserved and measure whether it is. And even at that target, MiroFish has not yet been calibrated. No one has measured what is preserved, and how much. Just as aeronautics got its correction tables only after it knew the Reynolds-number gap between real flight and the tunnel, the discourse wind tunnel too must first have that gap measured. Diversity preservation is the first candidate.
Read MiroFish as a predictor and you are wrong on two layers. One layer is principle: with the world's outcomes there isn't even a loop to connect to. The other layer is the scale: nothing has yet been measured about the discourse. Only when read as a hypothesis generator, a place for advance run-throughs, is this thing honest and useful. Feeding in a policy draft and seeing in advance which points of pushback jump out; changing the seed and watching where that pushback splits. Not prediction but rehearsal.
There is one contrast on this blog that fixes its place. If the recommendation algorithm was an engine that pushed society into its own shape (When a Bonus Rides on the Dashboard — A Metric Stops Reflecting the World and Becomes an Engine), MiroFish is a measuring instrument that tries to take the measure of discourse. The direction is reversed.
When I first saw this thing, I brushed it off as predictive-engine marketing. Now I see it as a discourse-rehearsal device. What changed was not the thing, but what I saw it as a scale model of.
The reason this distinction is not idle wordplay lies in the cost of misreading. Take a report from a discourse wind tunnel as a prediction of the world, and lay a policy or business decision on top of it, and the responsibility for the decision slides toward a machine that cannot answer to the world's outcomes. When it's wrong, there is no one left to hold to account.
What survives in the self-introduction "predicts everything" is not 'predict.' MiroFish previews, in advance, what people will say about everything — at an accuracy not yet calibrated. Hear that sound as prophecy and the thing breaks; hear it as rehearsal and it becomes useful. What's left to do lies not on the side of the thing but on the side of the one measuring: to inscribe a scale on this wind tunnel. Start by measuring diversity.
Sources
- The five-stage pipeline, interaction structure, persona and memory injection, backend LLM settings, recommended agent counts, the Shanda Group incubation relationship, and the original text of the self-description — the GitHub repo README (666ghj/MiroFish) and repo metadata and commit history (github.com/666ghj/MiroFish · api.github.com)
- The repo's registered official homepage is mirofish.ai alone. mirofish.my and mirofish.work, labeled 'marketing sites' in the body, are unofficial domains the repo does not link to, and are the source of the 'one million parallel agents' claim (the figure 'one million' itself matches the title of the paper behind OASIS, the engine MiroFish runs on, "One Million Agents")
- Reports of '10-day development' and a 30-million-yuan (about $4.1M converted) investment decision within 24 hours of the demo — 36kr (English edition, 2026-03-08), Sina Finance, TMTPost, and other Chinese outlets (2026-03-07 to 11). The wording is nearly identical, judged to be a single-origin spread
- Trending rank — Trendshift third-party tally (trendshift.io/repositories/16144). The table data reads #2 in Python daily and #3 overall, yet the site headline is marked '#1,' so an internal contradiction coexists
- Generative Agents (Smallville) — Park et al., "Generative Agents", arXiv:2304.03442. Evaluation section, TrueSkill ablation, information-diffusion figures, authors' limitations note
- Social Simulacra — Park et al., arXiv:2208.04024 (UIST'22). Failure-to-distinguish rate, designer responses, the "does not aim to predict" self-description
- OASIS (CAMEL-AI) — arXiv:2411.11581. The simulation engine MiroFish runs on, and the standard citation path to the Park-lineage research
- ABM origin — Schelling, "Dynamic Models of Segregation", J. Math. Sociology 1(2), 1971 · Santa Fe Institute 1987 conference institutional record (santafe.edu)
- "Validation is the central challenge for generative social simulation" (2025, PMC12627210) — points out the 35 studies' reliance on subjective evaluation
- Mou et al., ACM Computing Surveys v58n11 (2026-04, arXiv:2412.03563) · arXiv:2605.00197 (2026) — a survey of evaluation axes and "a standard has yet to emerge"
- 2024 U.S. election LLM prediction — arXiv:2411.03321 (v1 submitted before the election, v2 and v3 recast after the fact) · the confirmed result is the U.S. National Archives' Electoral College record (certified 2025-01-06)
- Silicon sampling — Argyle et al., arXiv:2209.06899 (Political Analysis, 2023). After-the-fact reproduction of past ANES surveys
- Independent follow-up validation — Cen et al., arXiv:2602.06302 (2026-02)
- The three-stage hierarchy of the law of similitude and "simultaneous agreement of all dimensionless numbers is nearly impossible in practice" — NASA TP-1435 (1979) and aeronautics-course textbooks, synthesized
- Completeness of the dimensionless-number list (dimensional analysis) — Buckingham, Physical Review 4, 345 (1914) and standard texts on dimensional analysis
- The Reynolds-number gap between wind tunnel and real aircraft, and cryogenic high-pressure tunnels — NASA/AIAA literature, synthesized
- The large-transport-aircraft case of scale-model / real-flight mismatch — via MDPI Aerospace 8(7):177 (2021). Primary source (AGARD AG-323) not reached
- Sharma et al., arXiv:2310.13548 (ICLR 2024) — quantification of sycophancy across five commercial assistants
- Laban et al., arXiv:2311.08596 — FlipFlop, correct answers flipping under pushback
- arXiv:2604.18005 (ACL 2026 Findings) · arXiv:2604.24698 (2026-04-27) — the structural cause of multi-agent diversity collapse, and persona fidelity amplifying stereotypes. Both very recent preprints
- Hegazy, arXiv:2410.12853 (2024-10) — improved debate performance from heterogeneous model combinations
- Berg/Nelson/Rietz (2008), Int'l J. Forecasting — long-run accuracy of the Iowa Electronic Markets
- Mellers et al. (2015), Judgment and Decision Making 10(3) — Good Judgment Project Brier scores (via an aiimpacts.org summary)
- Ensemble emergence (temperature, pressure) — standard statistical-mechanics texts